/01
You ask
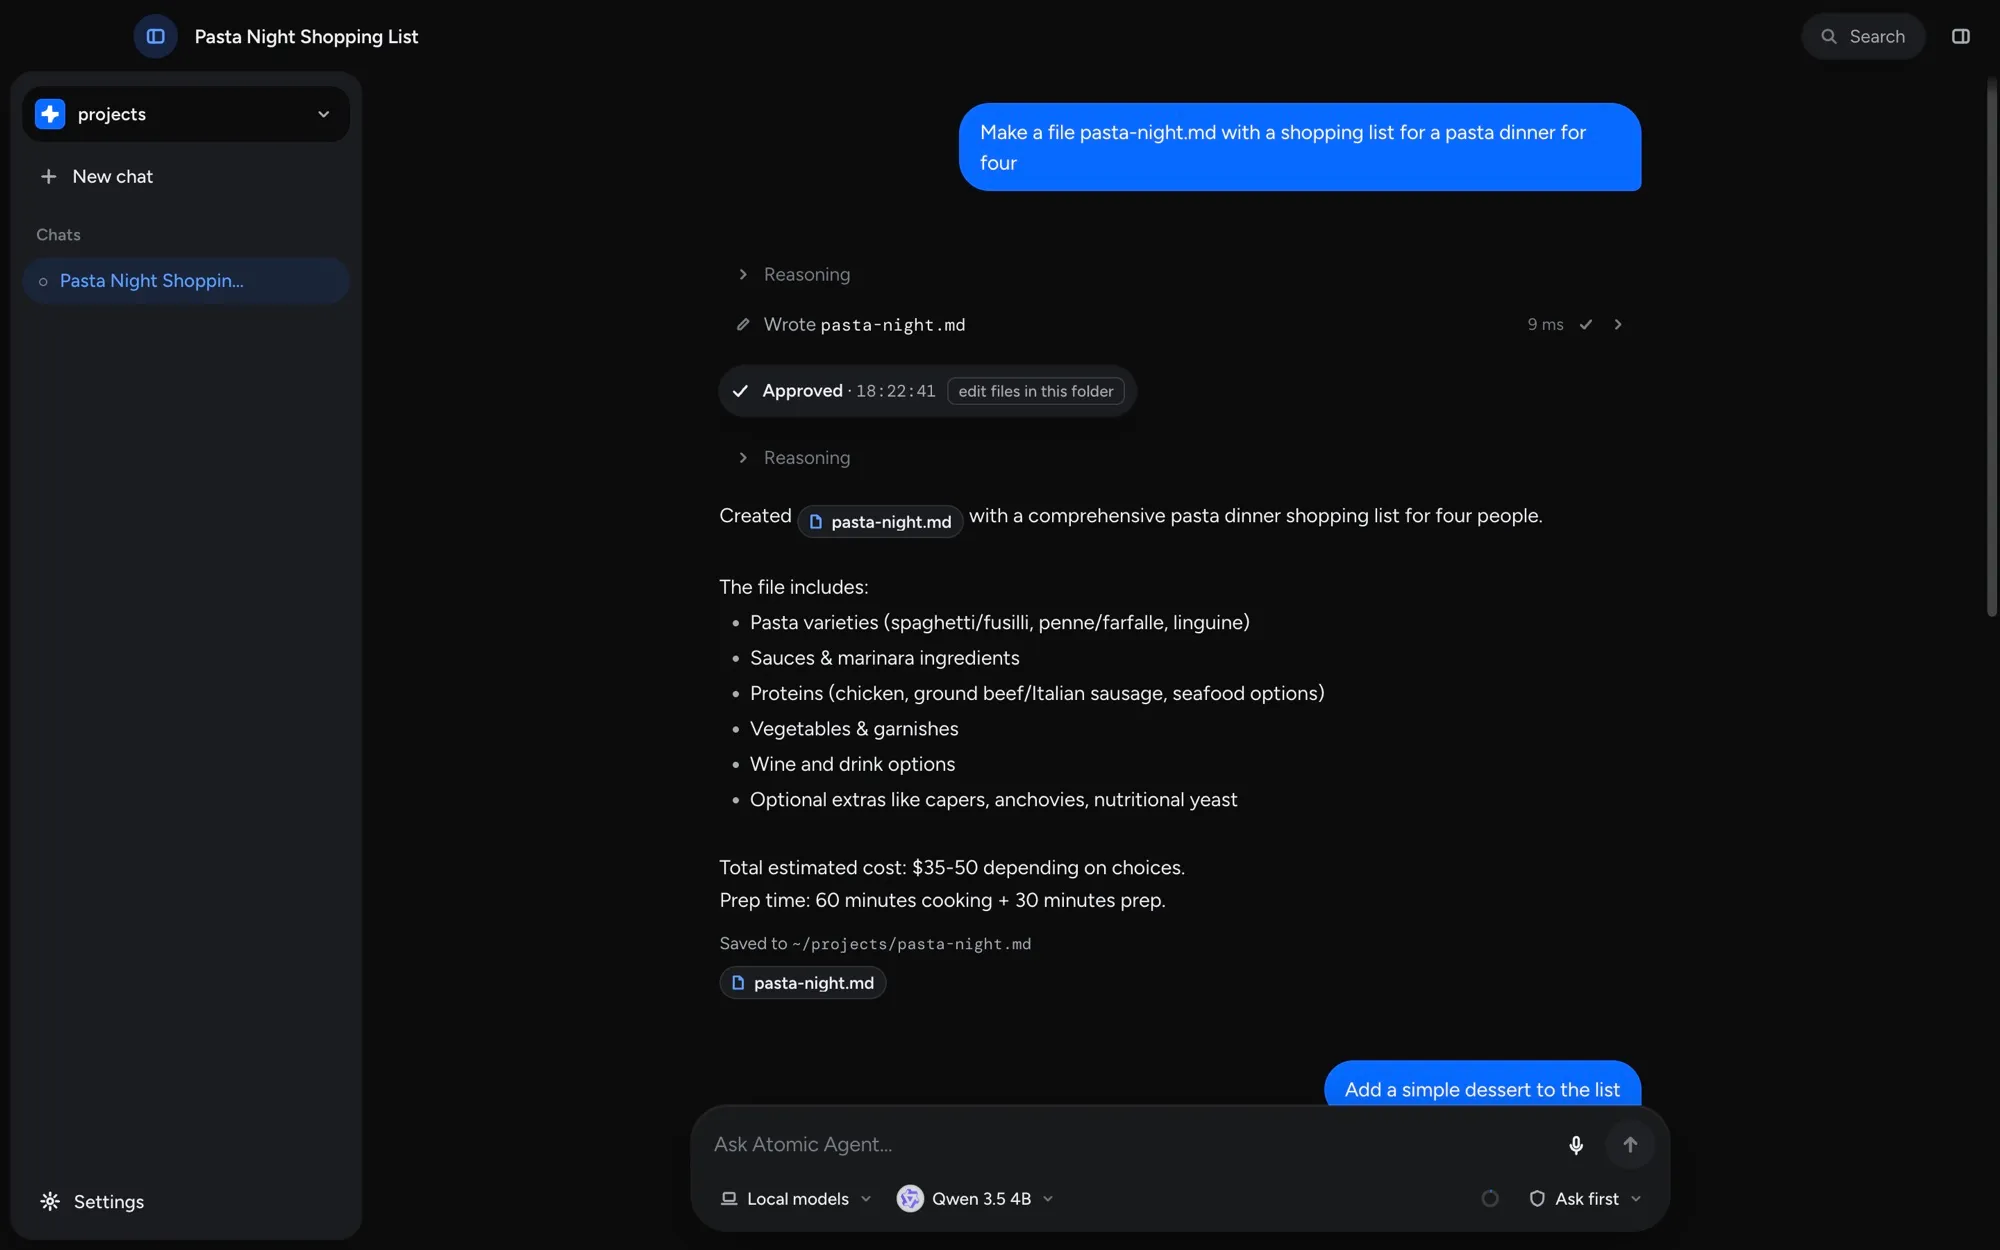
A task, in plain words, from the desktop app, the terminal or Telegram.
It runs on your hardware, talks to your model server, and keeps memory and chats in a local folder.
or install from the terminal
 Hermes Agent
GAIA Level 1 – 53 real-world tasks on the same model and same machine
Accuracy · GAIA Level 1
 Atomic Agent
 Hermes Agent
37/53 solved. Grammar-constrained decoding (GBNF) forces structurally-valid tool calls; bounded tails keep reasoning on-budget.
217s vs 351s. cache_prompt + slot_id reuse across steps, plus parallel read-only batches that overlap I/O after a single inference.
Grammar-locked actions and step-by-step checks mean Atomic Agent rarely walks into an unrecoverable wrong answer.
↻ the loop repeats – KV-cache keeps each step cheap, nothing re-sent to a server
A task, in plain words, from the desktop app, the terminal or Telegram.
One pass on your own GPU returns a list of next actions — grammar-locked, always valid.
Browser, files and shell — in parallel. Pauses for approval on risky steps.
Loops with cached context, so each step stays fast — until it replies or you stop it.
Questions or feedback? Grab 15 minutes with the team, any slot works.
Book a callthe engineering that keeps it fast, private, and running on your own machine
A byte-stable prompt prefix means every turn reuses the same cached compute. Nothing is re-encoded, and inference stays on your own hardware.
prefix ▓▓▓▓▓▓▓▓▓▓ cachedtail ░░░ re-computed────────────────────step N KV-cache HIT ✓
Grammar-constrained decoding forces structurally valid actions, even from tiny local models. How GBNF tool calling works
root ::= "[" call ("," call){0,15} "]"call ::= { "tool":…, "args":{…} }
Curated Q4 GGUF quants fit a long window on an everyday GPU.
fp16 ████████ ~24 GBq4 ██ ~6.7 GB
Recall injected in the tail, a few hundred tokens, cache intact.
SELECT content FROM memories_fts ORDER BY rank→ ~320 tokens
It pulls the backend and model for you. No accounts, no bills.
$ atomic-agent models startchat: started, healthy● on port 8080


 Atomic Agent on OpenRouter
Real production traffic: teams run Atomic Agent against cloud models through OpenRouter.
The desktop app is out for Mac, Windows and Linux. Download it here, then leave your email and we'll tell you when a new version ships.
Self-hosted AI agent, answered.
A self-hosted AI agent is an agent whose loop, model and data run on hardware you control, instead of a vendor cloud. Atomic Agent runs on your computer or server and keeps its memory and chats in a local folder.
It can download and manage llama.cpp for you, or connect to your own llama-server, Ollama, LM Studio or vLLM. Cloud providers such as OpenRouter are optional.
Yes. The terminal version runs as a service with scheduled tasks, and you can talk to it from Telegram or Discord. The browser tool can run headless.
With a local model, the model and your data stay on your machine. The app does send anonymous usage statistics and crash reports by default, and you can turn them off with one setting. Tools that browse or call APIs reach the network when you ask them to.
Yes. Atomic Agent is MIT-licensed. The only costs are your hardware and electricity, plus any cloud provider you decide to connect.
Be the first to know about new releases
We'll email you the download link.
Great news,
you are in!
You're subscribed.
We'll email you when a new release ships.